 IMPLICATOR
Implicator PRO Briefing / 17 Mar 2026
ChatGPT answers questions. Claude writes code. Gemini summarizes your inbox. All of them wait for you to show up, type something, and hit enter. OpenClaw does not wait.
OpenClaw is an open-source AI agent that lives on your hardware. Not a cloud service, not a browser tab. You wire it up to Telegram or WhatsApp (or both, or Slack, or 17 other channels), and it starts acting on what comes in. I have mine pulling my calendar at 7 a.m., sending the day's priorities straight to Telegram. Last Tuesday a broken PR hit CI on one of my repos and my phone lit up with the commit hash. I had not even turned on my laptop yet.
A chatbot talks. An agent acts.
This tutorial walks you through every step of setting up OpenClaw, from a blank terminal to a fully configured agent that messages you and remembers your preferences. No prior experience required. Every command is included, every config block explained.
Seven steps. That is the whole tutorial. By step four your agent will remember things between conversations. By step six it will message you on its own every morning. I spent about 40 minutes on my second run, though I had API keys already saved from earlier work.
What You Need to Know
- OpenClaw is a self-hosted Node.js agent runtime with 52 bundled skills, 20+ messaging channels, and support for every major AI model provider
- The entire memory system is plain Markdown on disk, fully readable and editable, with vector search for semantic recall across conversations
- Custom skills are just folders with a SKILL.md file, taking under five minutes to build from scratch
- Cron jobs run isolated sessions on a schedule with automatic delivery to any connected chat channel
What you are building
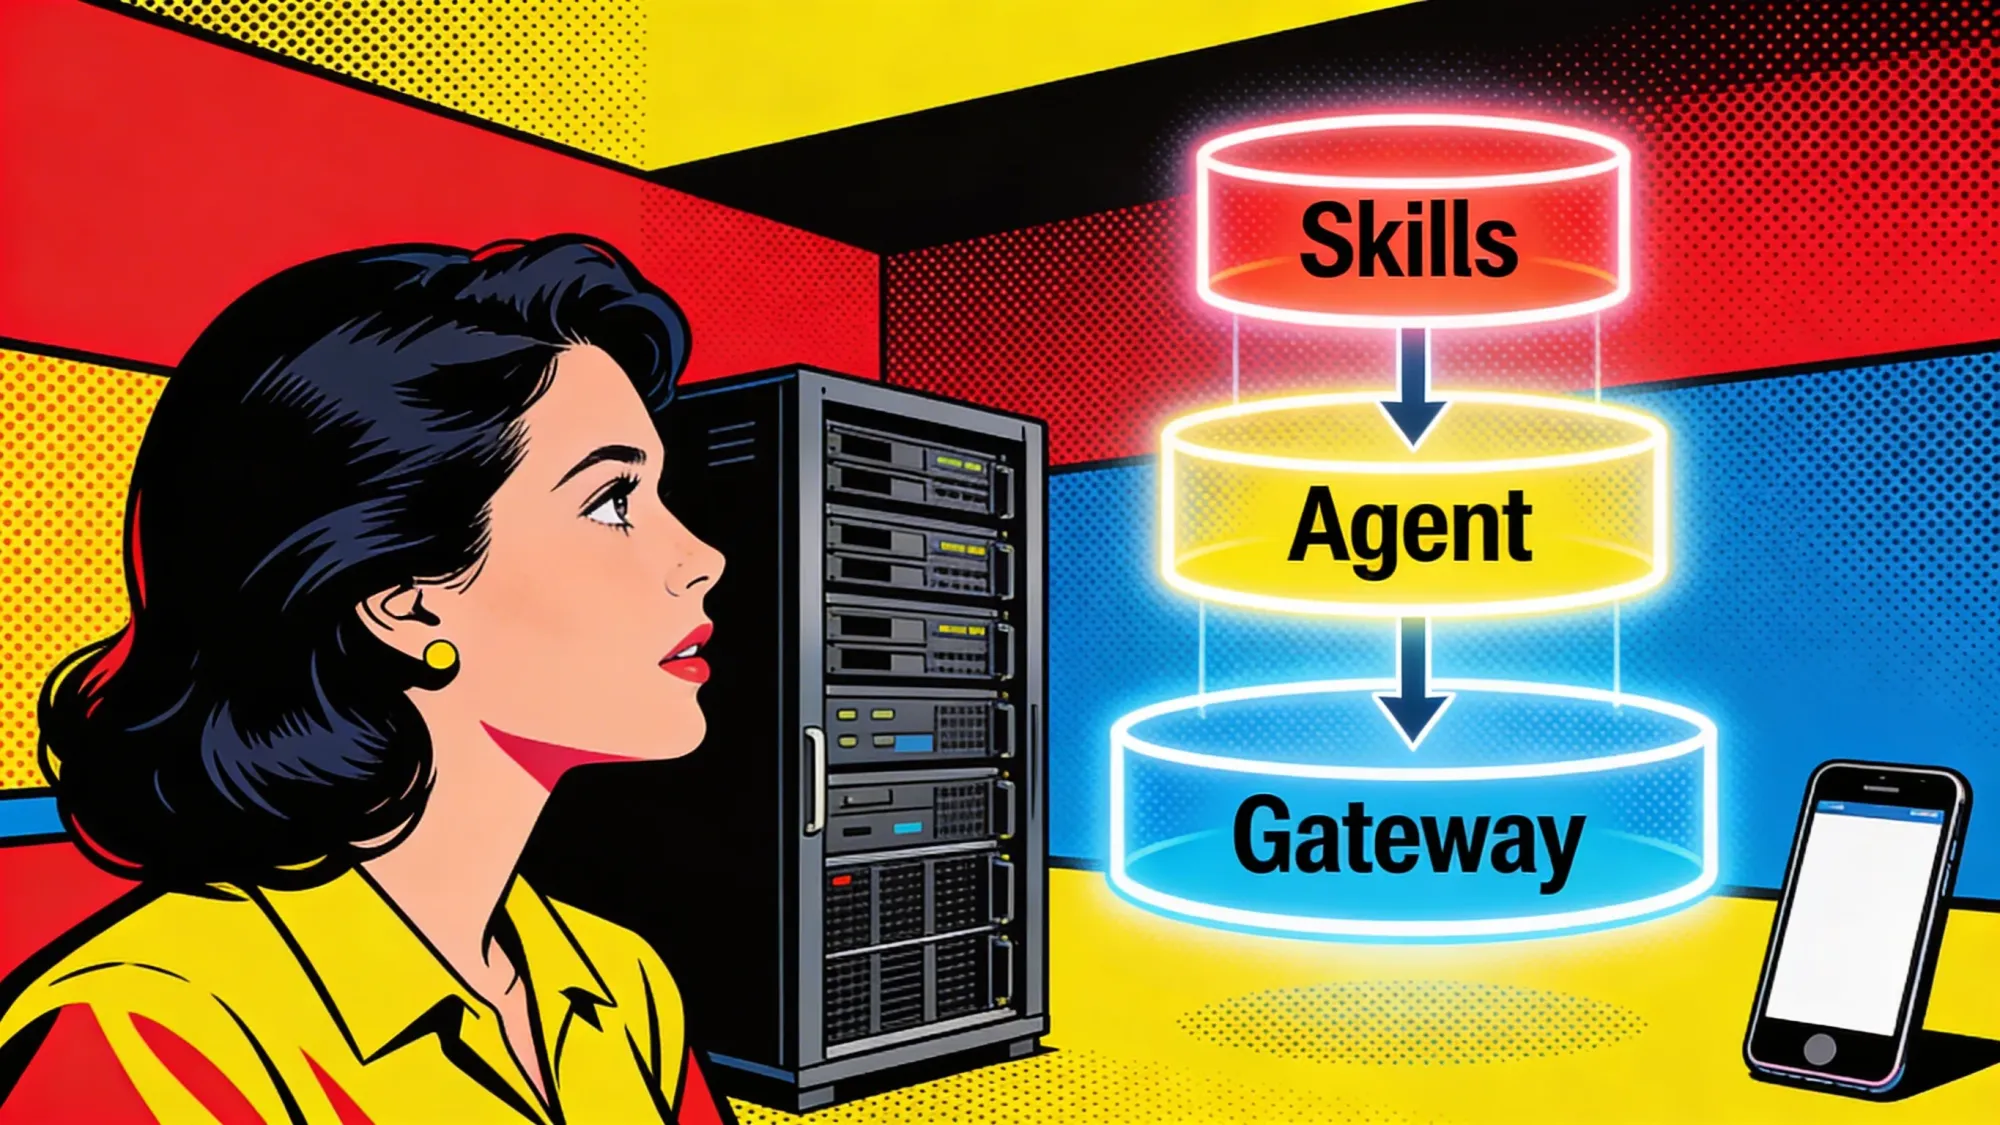
You know how a Docker container just sits there running until you kill it? OpenClaw works the same way. A Node.js process that starts and stays up. On one side it talks to your chat apps, on the other it talks to whatever AI model you configured. Messages flow both ways.
Three layers make this work. The Gateway handles all network traffic and session management, listening on a local WebSocket at ws://127.0.0.1:18789. It routes messages between channels, the agent, and the control interface. Above that, the Agent layer manages conversations, tool use, and memory. Skills handle the rest. Gmail, Spotify, GitHub, Obsidian, you name it. OpenClaw ships 52 out of the box and you can write your own in five minutes (more on that below).
Hardware is not picky. Mac, Linux, a Raspberry Pi collecting dust in a drawer. A $5/month Hetzner VPS handles it fine too. All you actually need installed is Node.js 22 or newer, plus an API key from Anthropic or OpenAI. Disk footprint is about 200 MB.
Two commands and you are running
Open a terminal. Two commands get you running:
npm install -g openclaw@latest
openclaw onboard --install-daemon
The onboard wizard walks you through initial configuration. It asks for your name, your preferred AI model, and an API key. If you have an Anthropic key, paste it here. OpenAI works too. You can always change this later.
Once onboarding completes, start the Gateway:
openclaw gateway --port 18789 --verbose
The --verbose flag prints every incoming message and routing decision to your terminal. Useful for the first run. Drop it later when the novelty wears off.
Test it by talking to the agent directly:
openclaw agent --message "What can you do?" --thinking low
You should get back a list of available tools. API error? Wrong key. Connection refused? Gateway is not running. The fix is usually obvious.
At this point the agent works, but only through your terminal. We need to give it a real messaging channel.
Give it a voice: Telegram first
OpenClaw supports over 20 messaging platforms. Telegram is the fastest to set up because Telegram's Bot API is free, instant, and requires no phone number verification handshake.
First, create a bot through Telegram's BotFather. Open Telegram, search for @BotFather, and send /newbot. Pick a name and username. BotFather gives you a token that looks like 123456:ABC-DEF1234ghIkl-zyx57W2v1u123ew11.
Now add it to your config. Open ~/.openclaw/openclaw.json (create it if it does not exist) and add:
{
  channels: {
    telegram: {
      enabled: true,
      botToken: "YOUR_BOT_TOKEN_HERE",
      dmPolicy: "pairing",
      allowFrom: []
    }
  }
}
Restart the Gateway. Then open Telegram and send any message to your bot. Because dmPolicy is set to "pairing", the bot responds with a pairing code. Approve it from your terminal:
openclaw pairing approve telegram <code>
That is the handshake. From now on, your Telegram chat with this bot goes straight to the agent. Ask it something, tell it to set a reminder. Messages flow through the Gateway to your model and the response comes back to Telegram. Feels like texting a very competent friend.
Prefer WhatsApp? Similar process, but you scan a QR code instead:
openclaw channels login whatsapp
QR code pops up in your terminal. Point your phone at it. Paired.
Both channels can run simultaneously. Add Discord, Slack, Signal, or any of the other supported platforms by extending the channels block in your config. Each channel gets its own allowFrom list and DM policy.
Pick a brain, add a backup
The default model from onboarding works, but you probably want more control. Model configuration lives in the agents section of openclaw.json:
{
  agents: {
    defaults: {
      model: {
        primary: "anthropic/claude-sonnet-4-5",
        fallbacks: ["openai/gpt-4.1"]
      },
      models: {
        "anthropic/claude-sonnet-4-5": { alias: "Sonnet" },
        "anthropic/claude-opus-4-5": { alias: "Opus" },
        "openai/gpt-4.1": { alias: "GPT" }
      }
    }
  }
}
Your primary field sets the default. When that model fails, whether from rate limits, outages, or billing issues, the fallbacks array kicks in automatically. OpenClaw tries each one in order until something responds.
Notice the models block. It acts as both a catalog and an allowlist. Only models listed here can be selected, and the alias field lets you switch from chat using short names:
/model Opus
Send that in Telegram and your next message uses Claude Opus instead of Sonnet. Harder problem, bigger model. Takes two seconds.
API keys go in your environment. Create ~/.openclaw/.env:
ANTHROPIC_API_KEY=sk-ant-...
OPENAI_API_KEY=sk-...
Or set them inline in openclaw.json:
{
  env: {
    vars: {
      ANTHROPIC_API_KEY: "sk-ant-...",
      OPENAI_API_KEY: "sk-..."
    }
  }
}
Both approaches work. The .env file is cleaner if you plan to version-control your config.
Memory is just Markdown
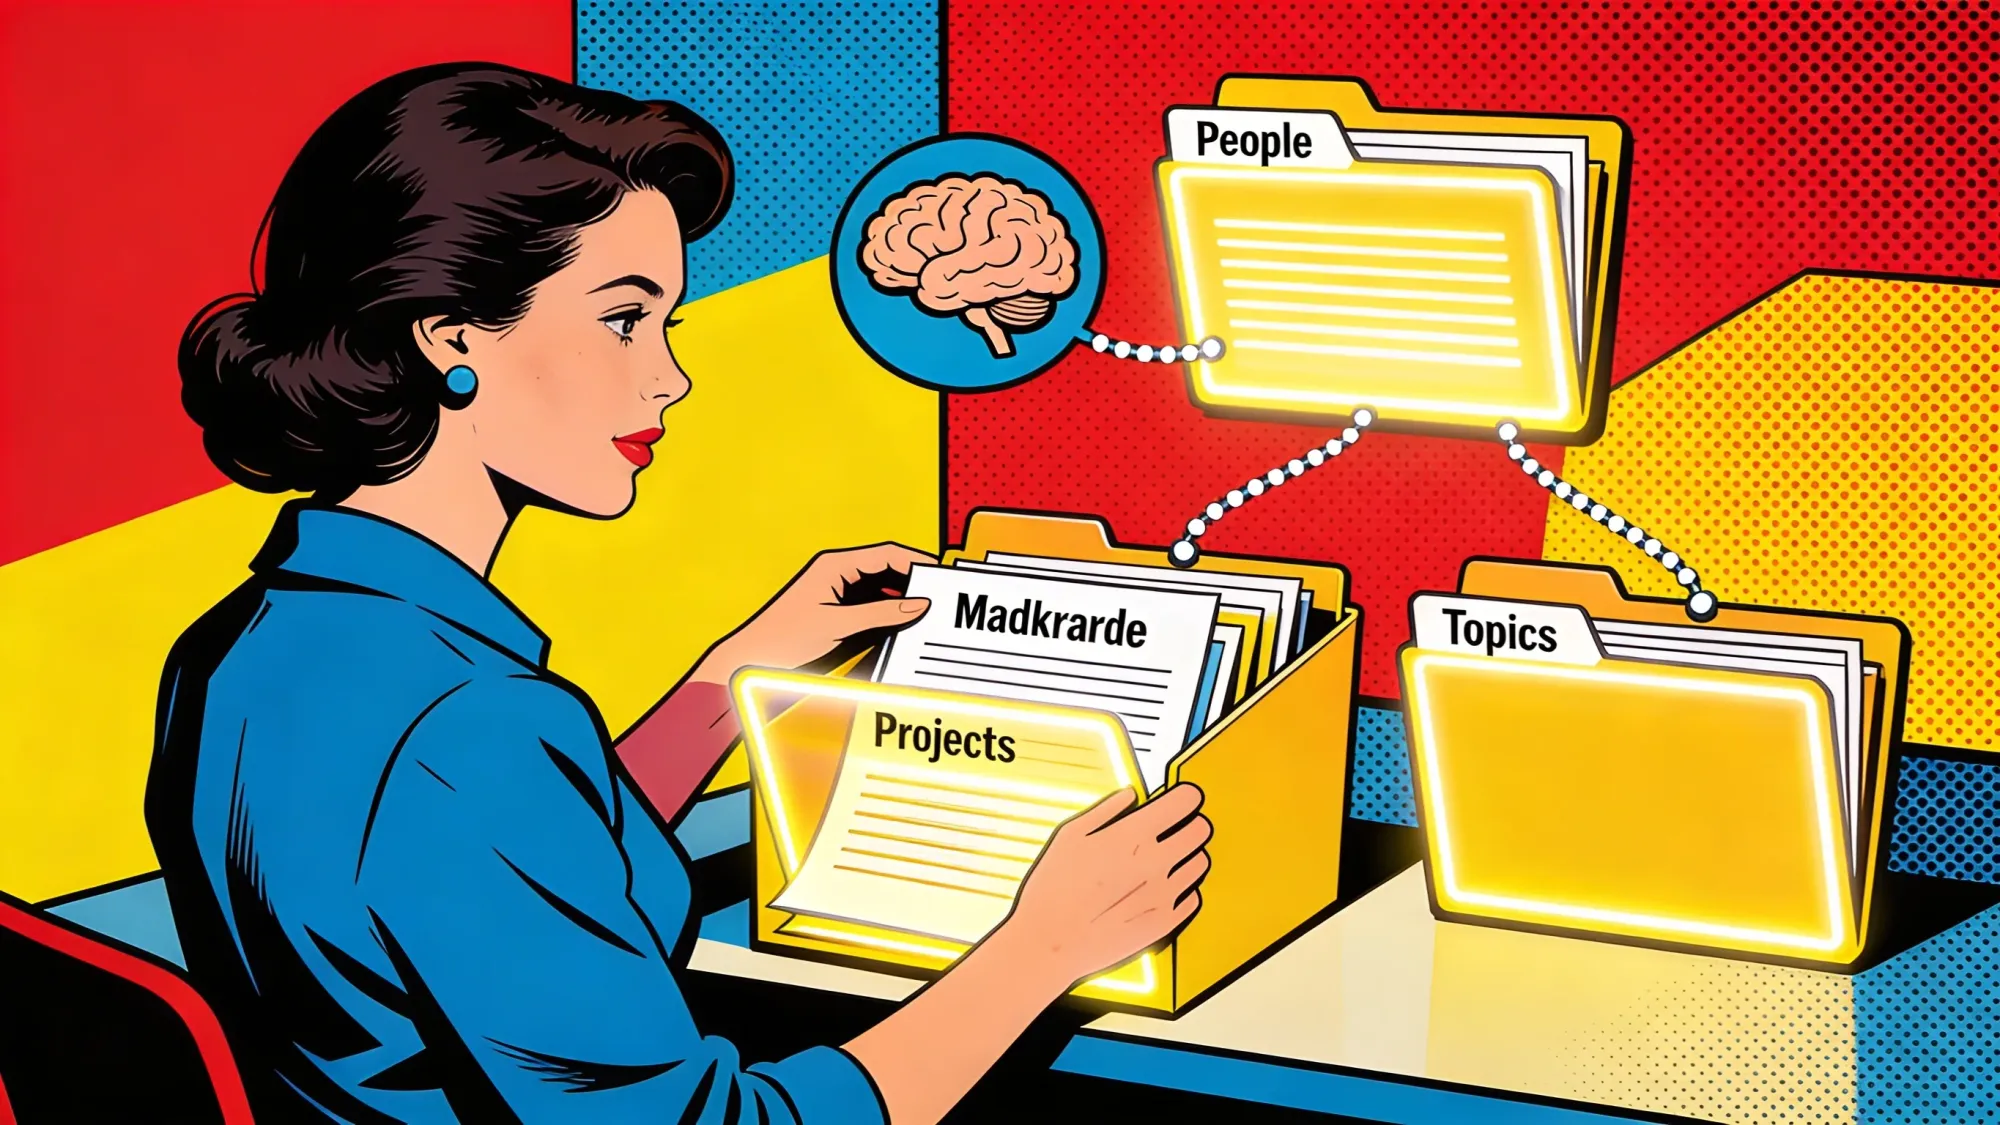
Most AI assistants forget everything the moment you close the window. OpenClaw writes memory to disk as plain Markdown files. You can read them, edit them, even commit them to Git.
The memory system has three tiers:
Tier 1: MEMORY.md. Loaded every single session. I keep mine around 80 lines. Your name, your timezone, the projects you are grinding on this quarter. Whatever the agent should already know before you type a word.
Create it manually:
mkdir -p ~/.openclaw/workspace
cat > ~/.openclaw/workspace/MEMORY.md << 'EOF'
# Core Context

- Name: [Your Name]
- Timezone: America/New_York
- Preferred communication: concise, no fluff
- Current projects: Q1 board deck, API migration
- Email: you@company.com
EOF
Tier 2: Daily context. Files at memory/YYYY-MM-DD.md capture running notes from each day's conversations. OpenClaw loads today's file and yesterday's at session start. The agent writes here automatically during conversations, logging decisions, action items, and context that matters for the day.
mkdir -p ~/.openclaw/workspace/memory
No need to create daily files yourself. The agent handles it.
Tier 3: Deep knowledge. Subdirectories under memory/ organize long-term knowledge by category:
memory/
  people/
    alice-chen.md
    bob-martinez.md
  projects/
    api-migration.md
    board-deck-q1.md
  topics/
    competitor-analysis.md
The agent writes to these when conversations surface durable information. You can also populate them manually with background material you want the agent to know.
Memory search
Without search, the agent can only access today's file and MEMORY.md. That is not enough. Enable vector search so the agent can recall information from weeks or months ago:
{
  agents: {
    defaults: {
      memorySearch: {
        provider: "openai",
        model: "text-embedding-3-small",
        enabled: true
      }
    }
  }
}
This uses OpenAI's embedding API to index your Markdown files and find relevant snippets when the agent needs them. Cost is negligible, fractions of a cent per search.
Want to keep everything local? Use a downloaded model instead:
{
  agents: {
    defaults: {
      memorySearch: {
        provider: "local",
        local: {
          modelPath: "hf:ggml-org/embeddinggemma-300m-qat-q8_0"
        }
      }
    }
  }
}
The model downloads automatically on first use. About 600 MB. After that, every search runs locally with zero API calls.
Automatic memory flush
When a conversation gets long, OpenClaw automatically compresses context. Before compressing, it triggers a memory flush, prompting the agent to write anything important to disk. Configure the threshold:
{
  agents: {
    defaults: {
      compaction: {
        reserveTokensFloor: 20000,
        memoryFlush: {
          enabled: true,
          softThresholdTokens: 4000
        }
      }
    }
  }
}
This means: when the conversation is within 4,000 tokens of the compaction threshold (which starts 20,000 tokens from the context window limit), flush memories to disk. The agent does this silently. You never see it happen.
Your first custom skill in five minutes
Skills are OpenClaw's plugin system. There are 52 bundled skills and hundreds more on ClawHub. Building your own takes less than five minutes.
A skill is a folder with a SKILL.md file. That is literally it.
Create a skill that checks Hacker News for trending AI stories:
mkdir -p ~/.openclaw/skills/hn-ai-digest
cat > ~/.openclaw/skills/hn-ai-digest/SKILL.md << 'SKILL'
---
name: hn-ai-digest
description: Fetches top Hacker News stories about AI and summarizes them
user-invocable: true
---

# HN AI Digest

When the user asks for an AI news digest or HN update:

1. Use the browser tool to fetch https://news.ycombinator.com
2. Identify the top 10 stories related to AI, machine learning, or LLMs
3. For each relevant story, extract the title, URL, points, and comment count
4. Summarize each story in one sentence
5. Format as a numbered list with title, link, points, and summary
6. End with a one-paragraph synthesis of the day's AI trends
SKILL
Restart the Gateway. Now send your agent:
Give me today's HN AI digest
The agent recognizes the skill, follows the instructions, fetches Hacker News, and delivers a formatted summary. No TypeScript, no deployment pipeline. Just Markdown.
For more complex skills that need external APIs or custom logic, you can add scripts alongside the SKILL.md:
mkdir -p ~/.openclaw/skills/hn-ai-digest/scripts
// scripts/fetch-hn.js
const res = await fetch('https://hacker-news.firebaseio.com/v0/topstories.json');
const ids = await res.json();
const top30 = ids.slice(0, 30);

const stories = await Promise.all(
  top30.map(async (id) => {
    const r = await fetch(`https://hacker-news.firebaseio.com/v0/item/${id}.json`);
    return r.json();
  })
);

const aiStories = stories.filter(s =>
  /\b(ai|llm|gpt|claude|gemini|openai|anthropic|machine.?learning)\b/i.test(s.title)
);

console.log(JSON.stringify(aiStories.map(s => ({
  title: s.title,
  url: s.url,
  score: s.score,
  comments: s.descendants
}))));
Reference the script in your SKILL.md instructions and the agent calls it when needed.
Want to install community skills instead of building your own? ClawHub has you covered:
clawhub install obsidian
clawhub install github
clawhub install spotify-player
Each skill appears in the agent's tool list immediately.
Make it proactive with cron
A personal AI agent that only responds when asked is just a chatbot with extra steps. Cron turns it proactive.
Here is the morning briefing I mentioned earlier. One command creates it:
openclaw cron add \
  --name "Morning briefing" \
  --cron "0 7 * * 1-5" \
  --tz "America/New_York" \
  --session isolated \
  --message "Check my calendar for today. Summarize any unread emails flagged as important. List my top 3 priorities based on recent context. Keep it under 200 words." \
  --deliver \
  --channel telegram \
  --to "tg:YOUR_TELEGRAM_ID"
What happens at 7 a.m. Eastern, Monday through Friday: the Gateway creates a clean session with zero prior history, executes the prompt, and pushes the output to your Telegram chat. No context from yesterday's conversations leaks in.
The --session isolated flag matters. Isolated sessions start clean, preventing scheduled tasks from accidentally referencing private conversations. Use --session main only when you want the cron job to access accumulated context from prior chats.
List your active cron jobs:
openclaw cron list
Remove one:
openclaw cron remove "Morning briefing"
Three schedule flavors: fixed times (--at "2026-03-15T09:00"), intervals (--every "30m"), or standard cron expressions. Jobs survive Gateway restarts. And if something fails? Exponential backoff. Thirty seconds, then a minute, then five, fifteen, sixty. The schedule resets after the next clean run.
openclaw usage or set billing alerts on your provider dashboard.
Lock it down before you walk away
OpenClaw runs on your machine and handles your messages. Security defaults are sane, but you should understand them. Skip this section at your own risk.
DM policy controls who can message your agent. Three modes:
"pairing"(default): Unknown senders get a pairing code. You approve from terminal. Best for personal use."allowlist": Only pre-approved contacts can reach the agent. Strictest."open": Anyone can message. Only use this for public-facing bots.
Sandboxing isolates tool execution. Enable it for all sessions:
{
  agents: {
    defaults: {
      sandbox: {
        mode: "all",
        scope: "session"
      }
    }
  }
}
With mode: "all", every tool invocation runs inside a sandbox. The scope: "session" setting gives each conversation its own isolated environment. This prevents a rogue skill or prompt injection from accessing files outside the workspace.
Separate accounts. Give your agent its own email address and cloud storage, separate from yours. Never hand over your primary credentials. If the agent does something unexpected, the blast radius stays contained.
Group chat safety. In group chats, require an explicit mention before the agent responds:
{
  channels: {
    telegram: {
      groups: {
        "*": { requireMention: true }
      }
    }
  },
  messages: {
    groupChat: {
      mentionPatterns: ["@openclaw"]
    }
  }
}
This prevents the agent from jumping into every group conversation uninvited.
Where to go from here
Everything from here is optional, and that is the point. OpenClaw ships a working agent in 45 minutes. What you bolt on next depends entirely on your workflow.
Multi-agent routing lets you run separate agents for work and personal life, each with its own workspace and model. Browser automation gives the agent a managed Chrome instance for web tasks. Voice mode on macOS, iOS, and Android adds hands-free interaction through wake words.
Run openclaw doctor periodically to check for configuration issues and pending migrations. Run openclaw update --channel stable to stay on the latest stable release.
Full config reference at docs.openclaw.ai. Community skills at ClawHub. And the source code is MIT-licensed, so you can read every line before handing it your calendar access.
Will it actually replace the half-dozen apps you juggle? Depends on how far you push the skills and automations. But the starting cost is two terminal commands and a free-tier API key, which makes the experiment cheap enough to just try.
What to watch
- OpenClaw v2026.3.x releases: Memory compaction improvements landed in late February. The March releases should stabilize the hybrid search system, watch the changelog for BM25 tuning fixes
- ClawHub skill count: The registry passed 100 managed skills in February 2026. Growth rate suggests 200+ by summer, expanding what the agent can do out of the box
- Multi-agent routing adoption: The feature shipped recently and real-world patterns are still forming. Watch the community Discord for production configs worth copying
- Local model support via Ollama: Running a local LLM as your primary model removes API costs entirely. KVM4-class VPS hardware (32 GB RAM) makes this practical for smaller models
Key Takeaways
- Five-minute skills: OpenClaw's SKILL.md format means you can prototype a new agent capability in less time than it takes to write a Jira ticket about it
- Memory is files: Unlike opaque vector databases, OpenClaw stores everything as Markdown you can read, edit, grep, and version-control, giving you full auditability
- Fallback routing prevents outages: Configuring a secondary model means your agent keeps running during provider downtime, something most chatbot setups cannot do
- Isolation matters more than you think: Sandboxed sessions and pairing-based DM policy are not paranoia but production hygiene for any agent handling personal data
- Cron changes the relationship: The shift from reactive chatbot to proactive agent happens the moment you add your first scheduled task, that is when it stops being a tool and starts being infrastructure
- Cost stays low: A Claude Sonnet-powered agent with daily cron jobs and moderate chat usage runs about $3-8/month in API costs, less than most SaaS subscriptions
Sources & Further Reading
Primary Sources
- OpenClaw GitHub Repository — Full source code, MIT licensed
- OpenClaw Documentation — Official configuration reference, skill guides, and architecture docs
- Gateway Configuration Reference — Complete JSON5 config field reference
- Skills Documentation — SKILL.md format, gating, and ClawHub integration
Research & Analysis
- Memory System Architecture — Vector search, hybrid BM25, compaction, and flush configuration
- Cron Jobs Documentation — Schedule types, execution modes, and delivery configuration
- OpenClaw: Complete Guide to the Open-Source AI Agent — Milvus Blog deep dive on architecture and history
Further Reading
- ClawHub Skill Registry — Browse and install community skills
- How to Create OpenClaw Custom Skills — APIDog tutorial on advanced skill patterns
- OpenClaw Memory Masterclass — Deep dive on memory configuration and optimization
Free AI briefing · Weekdays
The AI stories that matter, sourced and explained.
Join the Morning Briefing. It goes out every weekday at 4:45 a.m. Pacific, with later sends for the East Coast, Berlin and Tokyo.
Free when you sign up: The Paperclip Compendium, our tested guide to running AI agents.
Free. Unsubscribe in one click.
Marcus Schuler
Editor-in-Chief and founder of Implicator.ai. Former ARD correspondent and senior broadcast journalist with 10+ years covering tech. Writes daily briefings on policy and market developments. Based in San Francisco. E-mail: editor@implicator.ai