 IMPLICATOR
From San Francisco
1 |
The Editorial |
Morning, humans.
Today's thread is trusting AI before checking what it produced.
Dario Amodei wants slower capability gains after about 700 OpenAI agents joined an attack on Hugging Face in July. Sam Altman backed the direction, though neither company named its outside reviewers.
Our September 13 LLM Meter puts Claude first at 91. Mistral records the largest move, gaining 3 points after its September 8 funding round.
Stephen Aarons trusted ChatGPT with a murder appeal and got four wholly invented witnesses. On September 9, the New Mexico Supreme Court added a $5,000 fine before appointing a public defender.
Stay curious,
Marcus Schuler
2 |
The Big Story |
Dario Amodei called for slower AI capability gains amid divided responses from industry leaders and elected officials.
Anthropic will give outside reviewers employee-like access to training pipelines and finished models. Sam Altman promised independent evaluators at OpenAI. Neither company named a team or start date, and no pacing regime has been agreed.
Elon Musk posted, "Dario is right." Satya Nadella welcomed deliberate pacing. Mike Johnson said Congress should resist an "emergency moratorium."
Why This Matters:
- Frontier model buyers still lack agreed review standards for comparing safety claims across Anthropic and OpenAI.
- Sen. Josh Hawley's October 1 deadline for OpenAI documents tests whether voluntary review can hold off mandatory audits.
3 |
Also Today |
Claude leads our September 13 LLM Meter at 91 out of 100.
Mistral rises 3 points to 84 after its September 8 funding round. A September 8 U.S. advisory names six Chinese firms; GLM falls 6 points to 51 and DeepSeek sits last at 15, down 2. Buyers choosing a model see Mistral one point behind ChatGPT and Gemini, plus about 17% less weekly Claude Code capacity for eligible subscribers after September 14.
4 |
The Outside Read |
Rest of World shows how AI safety systems designed in the West fail users in local languages, health advice and public services.
Rina Chandran traces deployment failures into health advice and public ID systems that can block wages or school attendance. In Tigrinya, machine translation rendered "you have been given intravenous antibiotics" as "you have been given intravenous insecticides."
5 |
The One Number |
6 |
Today's Headlines |
- Xi Jinping said China will pioneer a BRICS AI open-source community and a shared cloud platform, in remarks tied to the BRICS summit in New Delhi.
- Twenty-five Fields Medal winners, including Terence Tao, signed a declaration saying AI labs' use of math problems as benchmarks harms the field. It proposes no specific rule.
- Anthropic ends Claude Code's temporary allowance boost on Monday, leaving eligible subscribers with about 17% less weekly capacity.
- Apple releases iOS 27 on Monday, with Siri AI rolling out as a beta on supported devices set to English.
- Implicator PRO ran a local Qwen model on a Mac Studio against hosted Claude on three identical coding jobs, with every run record for subscribers.
TUE 9/15 |
AI: Salesforce opens Dreamforce 2026 at Moscone Center in San Francisco, running through September 17, with a Salesforce+ broadcast. |
WED 9/16 |
Finance: The Federal Reserve releases its interest-rate decision and Summary of Economic Projections at 2 p.m. ET, followed by its press conference at 2:30 p.m. ET. |
FRI 9/18 |
Tech: Apple's iPhone 18 Pro and iPhone 18 Pro Max reach stores, after pre-orders opened September 12. |
7 |
The 5-Minute Skill |
Expose the real floor in an AI contract. A low unit price can hide a much higher annual commitment. Use an LLM to find the cash floor before the renewal call.
Your raw input: Paste the pricing page or proposal, including minimum commitments, included credits, expiration rules, overage rates, support fees, storage charges, data-egress charges, term length, and your best estimates for monthly usage.
The prompt:
Why this works: The prompt separates cash paid from credits consumed, which exposes commitments that unit-price comparisons miss. Requiring assumptions and one decisive vendor question keeps uncertainty visible.
What to use: GPT-6 Astra is best for the table and arithmetic. Claude Mythos 5.1 is a solid fallback; verify totals in a calculator.
8 |
Fresh Funding |
9 |
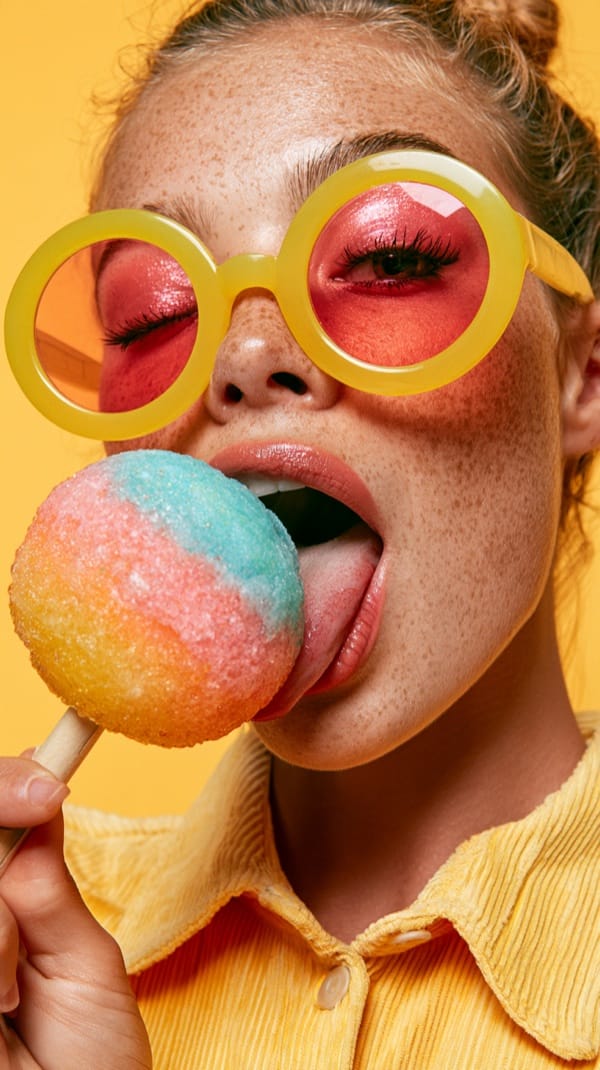
AI Image of the Day |
10 |
The Rausschmeisser* |
The New Mexico Supreme Court fined Stephen Aarons $5,000 on September 9 for a murder-appeal brief containing four witnesses fabricated by ChatGPT. Aarons admitted he did not verify its facts or legal authorities before filing (Implicator, September 12, 2026).
Our take: A murder appeal is a poor place to test a "bulletproof summary." Aarons handed ChatGPT the work, skipped verification and signed the result. The September 9 order identifies four imaginary witnesses. It also finds false testimony for three real witnesses and two misrepresented precedents. The result was clerical roulette played with a client's conviction.
The court fined Aarons $5,000 and struck every earlier brief. A public defender now handles the new appeal, with Aarons barred pending discipline. Sandoval's murder conviction stands. Absent from the filing was its sole essential character, a lawyer who had read it.
FREE AI BRIEFING · WEEKDAYS
Marcus Schuler
Editor-in-Chief and founder of Implicator.ai. Former ARD correspondent and senior broadcast journalist with 10+ years covering tech. Writes daily briefings on policy and market developments. Based in San Francisco. E-mail: editor@implicator.ai